NeurIPS 2025Generative video watermarking

Safe-Sora: Safe Text-to-Video Generation
via Graphical Watermarking

Graphical watermarks embedded during generation.
From adaptive matching to watermark recovery.

Zihan Su1 Xuerui Qiu2 Hongbin Xu3 Tangyu Jiang 1 Junhao Zhuang 1
Chun Yuan1 † Ming Li4 † Shengfeng He5 Fei Richard Yu4
1 Tsinghua University 2 Institute of Automation, Chinese Academy of Sciences
3 South China University of Technology
4 Guangdong Laboratory of Artificial Intelligence and Digital Economy (SZ)
5 Singapore Management University
†Corresponding Author
Match

Coarse to fine

Adaptive patch matching
Embed

Spatiotemporal fusion

3D wavelet-enhanced Mamba
Recover

Watermark extraction

Reconstruction under distortions
Video + graphical watermarkInteractive examples

Create. Protect. Recover.

Graphical watermarks, embedded during generation.
OriginalWatermarkedDifference ×5
Generated video comparison
Original watermarkRecovered watermarkDifference ×5
Original watermark, recovered watermark and difference magnified five timesWatermark reconstruction

Safe-Sora is the first framework that integrates graphical watermarks directly into the video generation process. The following results show the original video, the watermarked video, the difference between them (×5), the original watermark, the recovered watermark, and the difference between them (×5).

The idea

Watermark protection,
built into generation.

AI-generated videos need reliable copyright protection. Embedding an invisible graphical watermark requires preserving both video quality and the recoverability of the watermark.

Safe-Sora embeds graphical watermarks directly during video generation. Adaptive patch matching aligns watermark content with video regions, while wavelet-enhanced Mamba supports embedding and recovery across frames.

Read the full abstract ↗
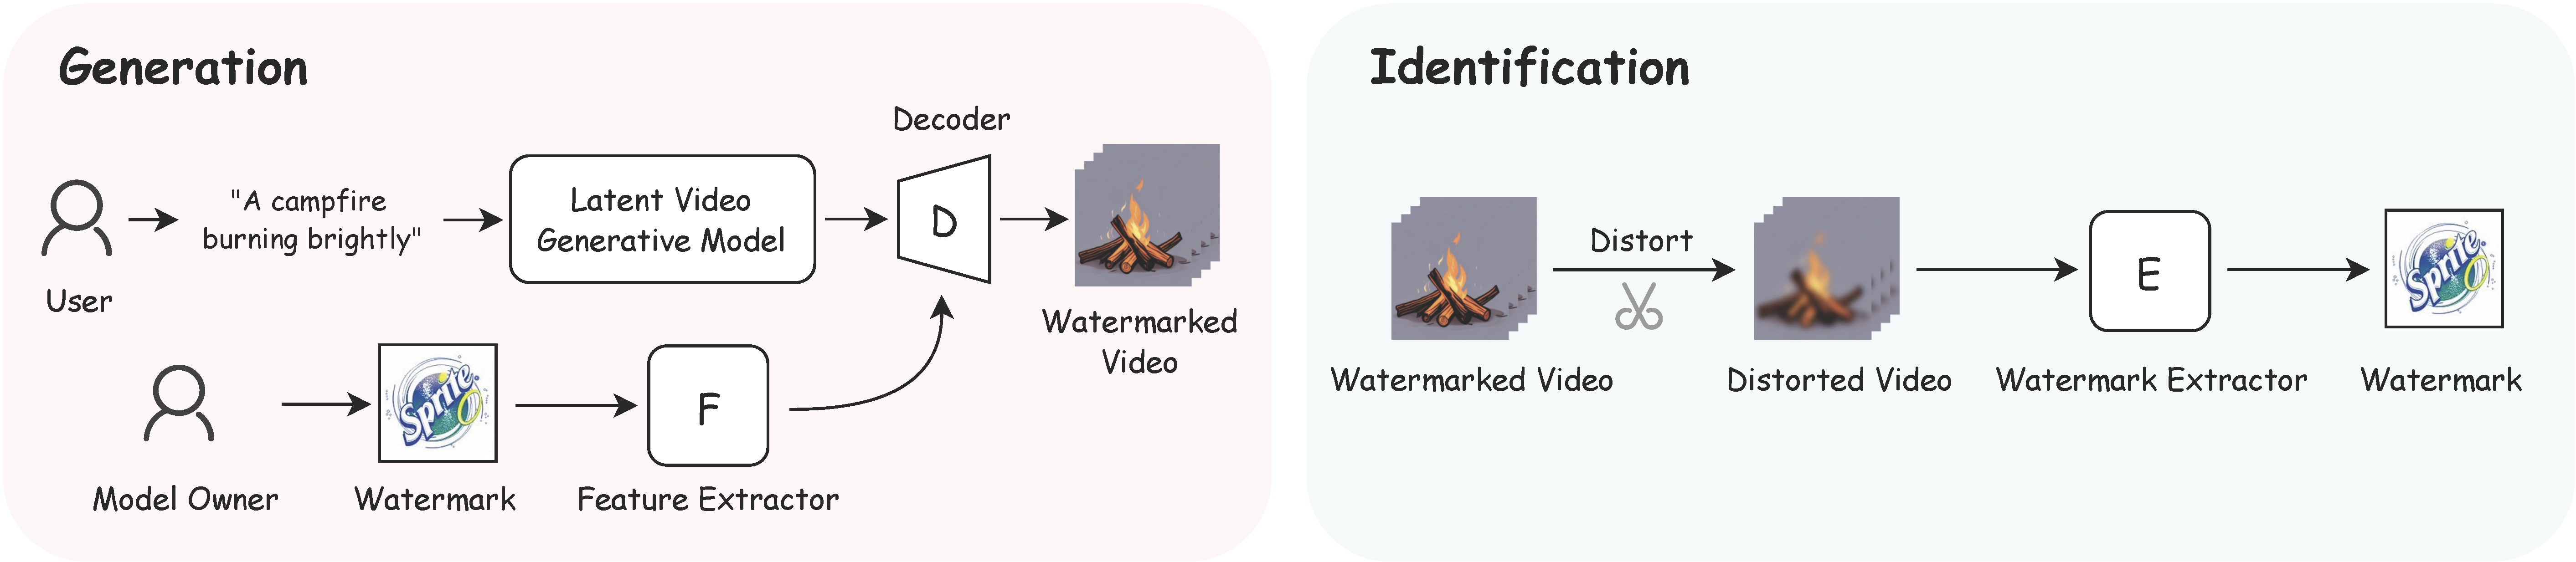
Graphical watermark embedding and identification.
02

From adaptive matching to recovery

Overview of our Safe-Sora framework. Our method consists of three main components: 
      (1) Coarse-to-Fine Adaptive Patch Matching: partitioning the watermark image into patches
Overview of our Safe-Sora framework. Our method consists of three main components: (1) Coarse-to-Fine Adaptive Patch Matching: partitioning the watermark image into patches and optimally assigning them to appropriate video frames and regions, followed by patch embedding and upsampling to generate the watermark feature map; (2) Watermark Embedding: the watermark feature map is fused with multi-scale video features via a UNet with 2D SFMamba blocks, followed by a series of 3D SFMamba blocks that implement our spatiotemporal local scanning strategy, to produce the watermarked video; (3) Watermark Extraction: recovering the embedded watermark using an extraction network built with a distortion layer, a series of 3D SFMamba blocks, and position recovery.
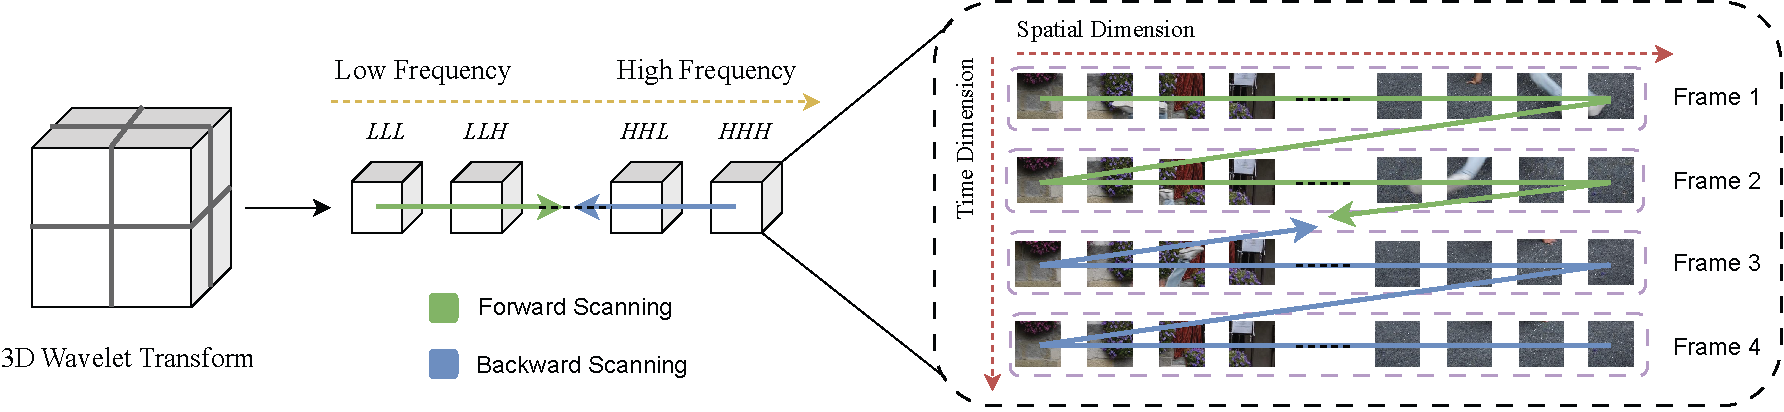
Spatiotemporal local scanning strategy. For 3D frequency scanning, we propose a spatiotemporal local scanning strategy for 3D wavelet transform, which processes the frequency compo
Spatiotemporal local scanning strategy. For 3D frequency scanning, we propose a spatiotemporal local scanning strategy for 3D wavelet transform, which processes the frequency components hierarchically from low frequency to high frequency and high frequency to low frequency.
03

Quality, fidelity, and robustness


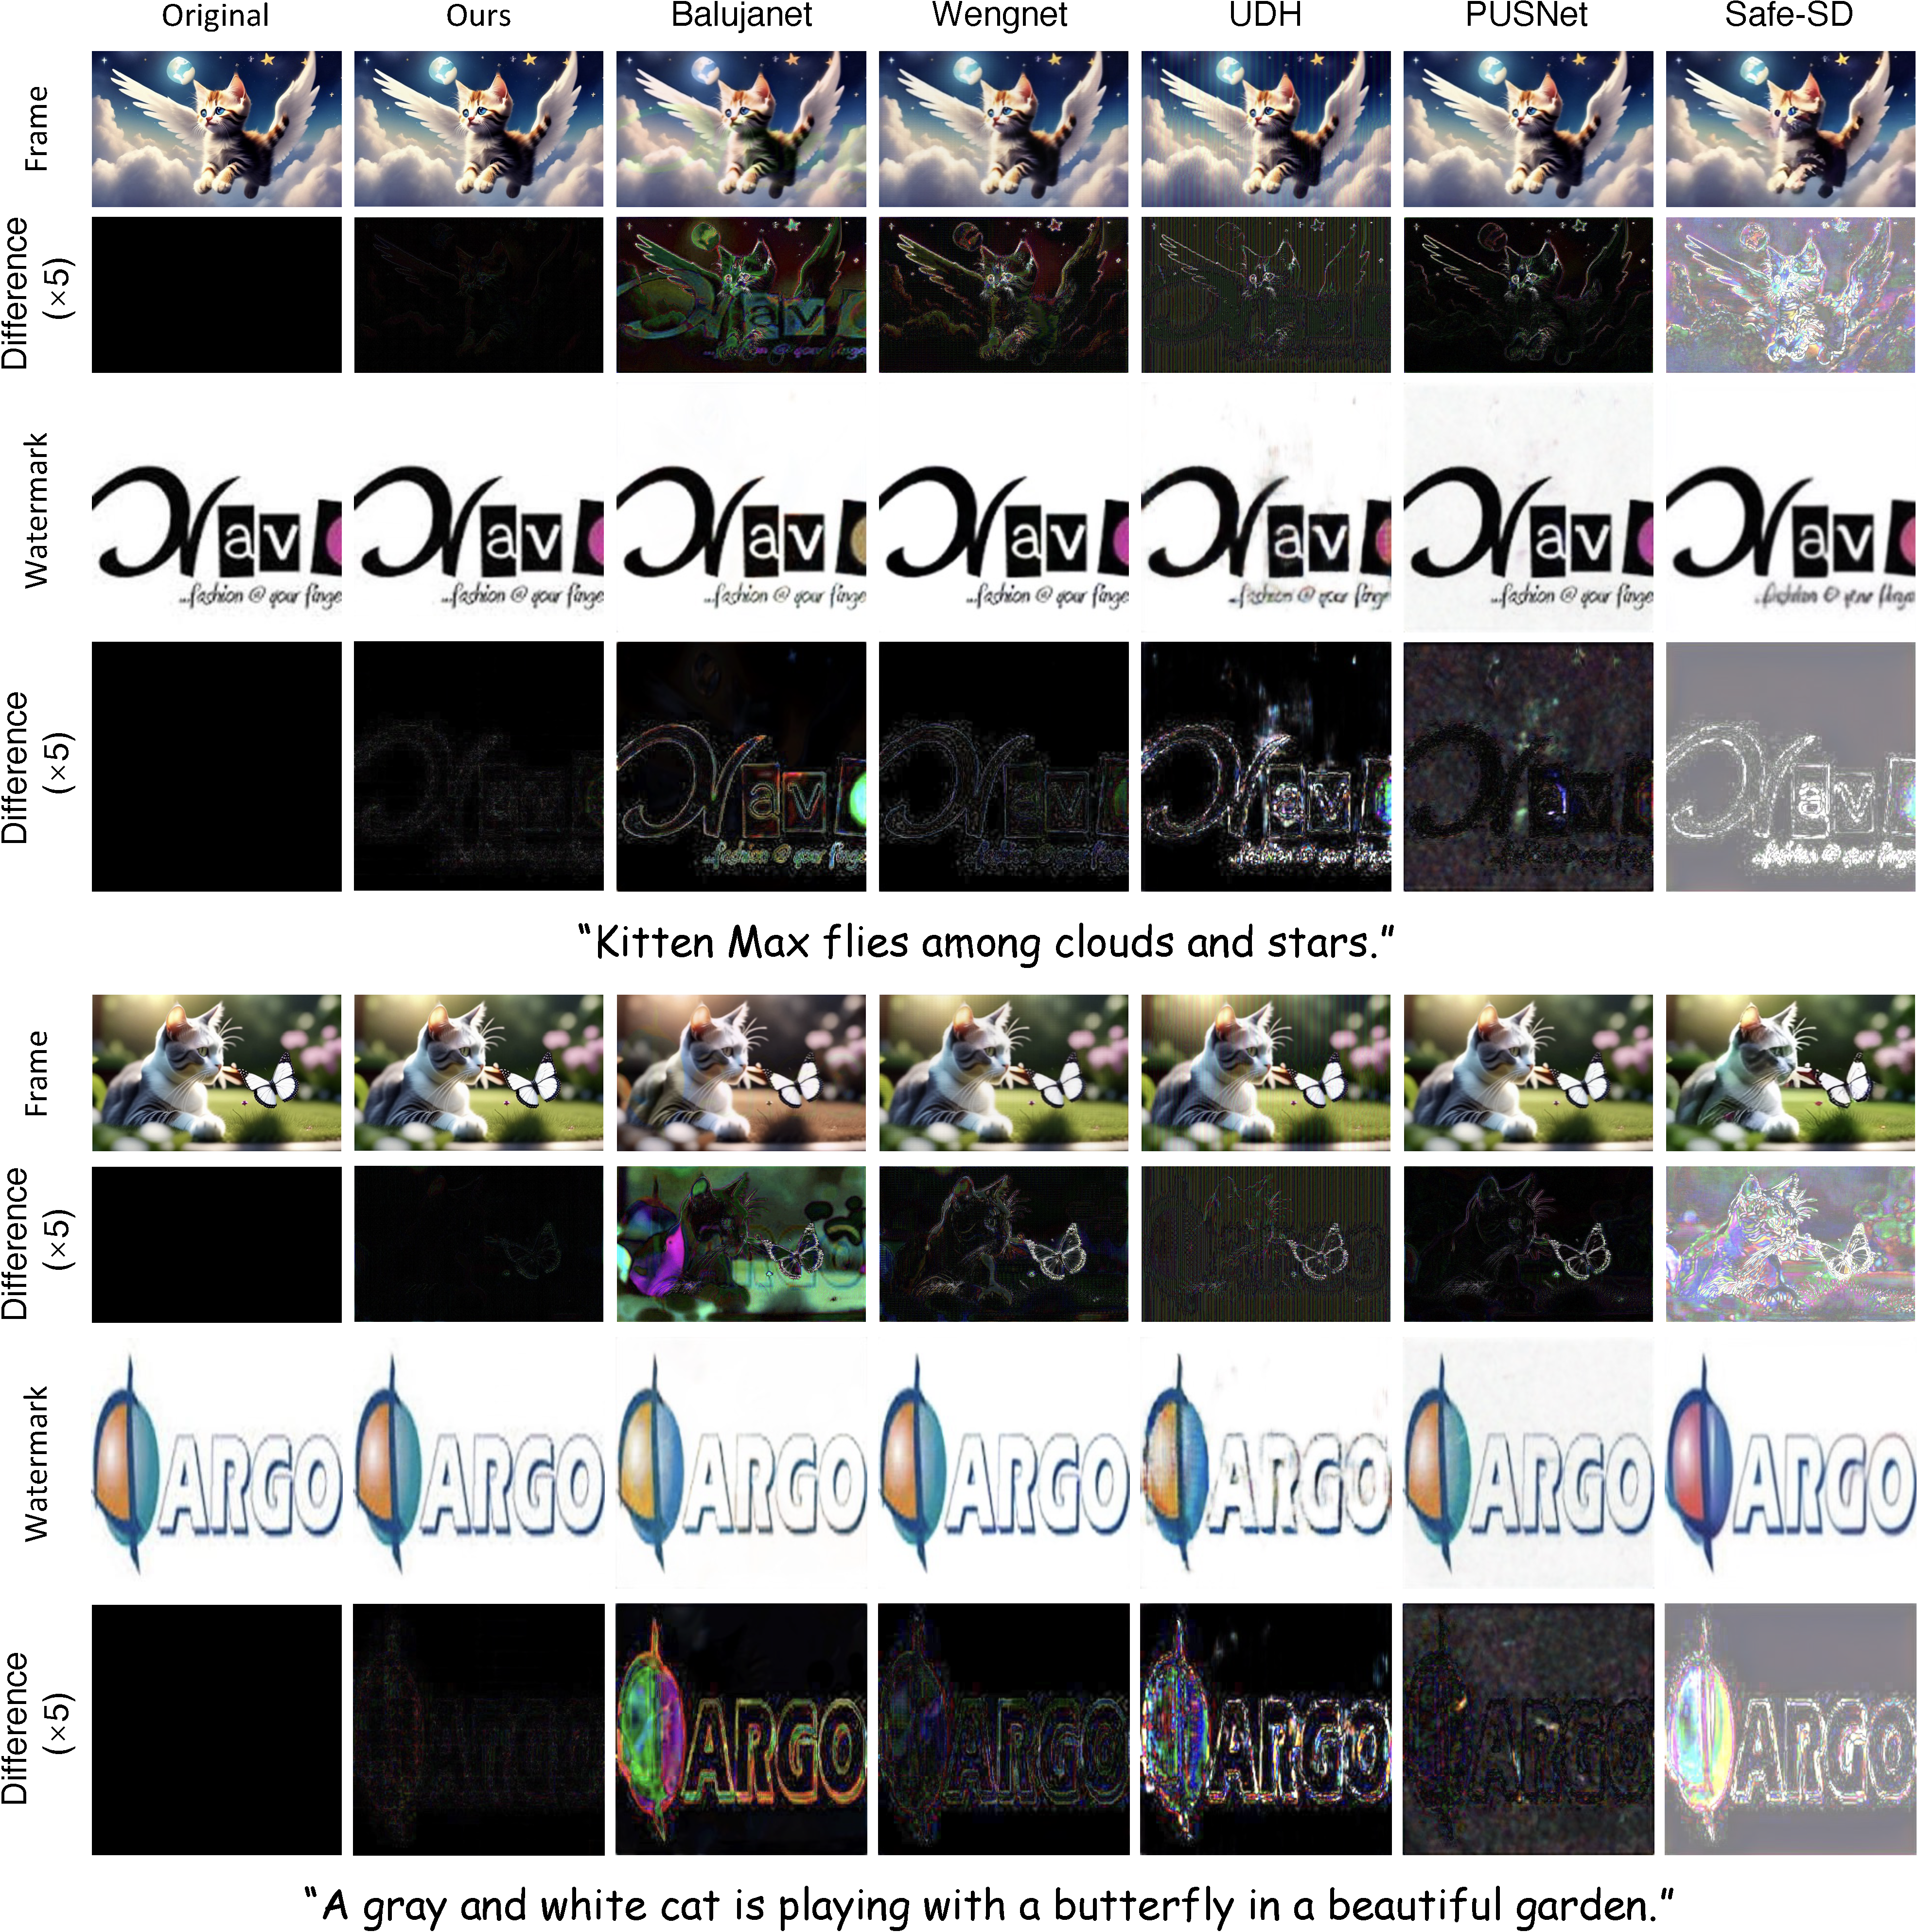
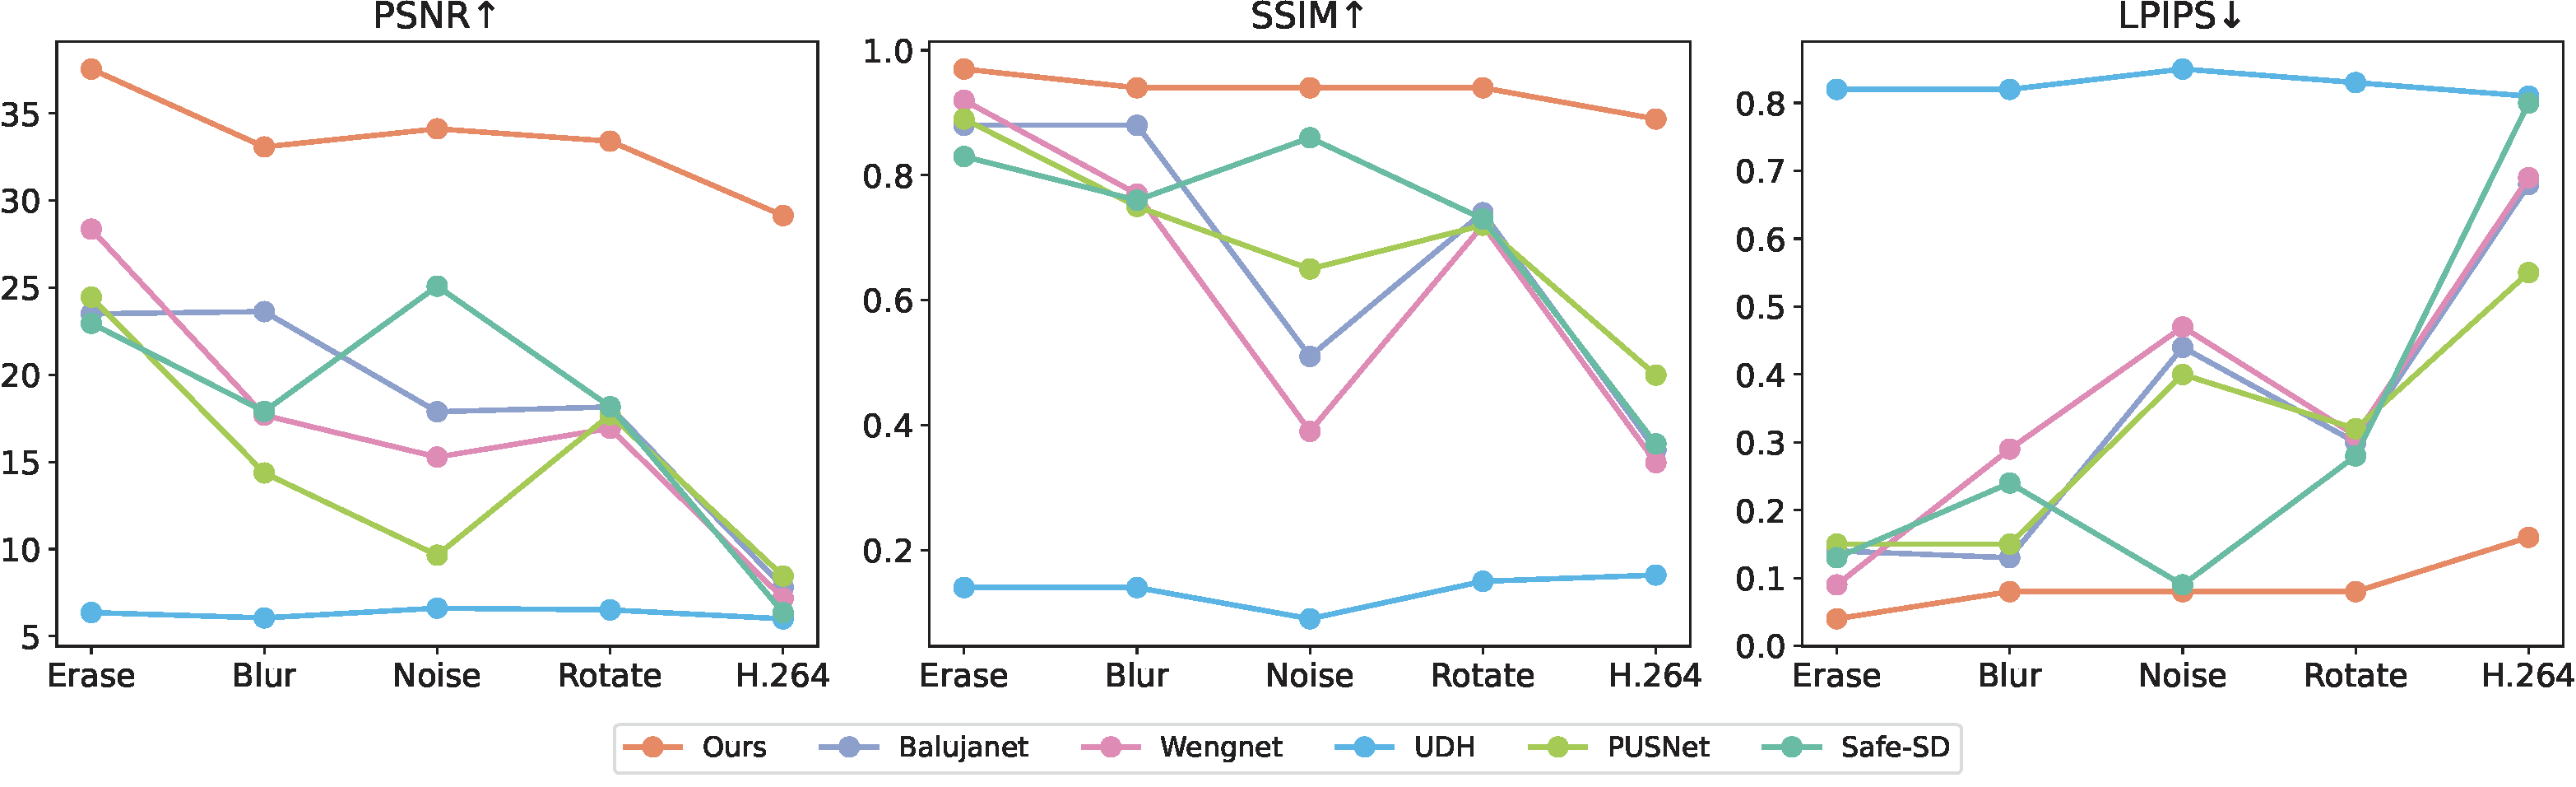
      Qualitative comparison results.
      Difference maps show absolute differences between the watermarked and original videos, and between the recovered and original watermark
Qualitative comparison results. Difference maps show absolute differences between the watermarked and original videos, and between the recovered and original watermarks.
04

Cite this work

@article{su2025safe,
  title={Safe-Sora: Safe Text-to-Video Generation via Graphical Watermarking},
  author={Su, Zihan and Qiu, Xuerui and Xu, Hongbin and Jiang, Tangyu and Zhuang, Junhao and Yuan, Chun and Li, Ming and He, Shengfeng and Yu, Fei Richard},
  journal={arXiv preprint arXiv:2505.12667},
  year={2025}
}
Enlarged paper figure